Match4Annotate
Transferring point and mask annotations across independently acquired ultrasound videos without target-side labels.
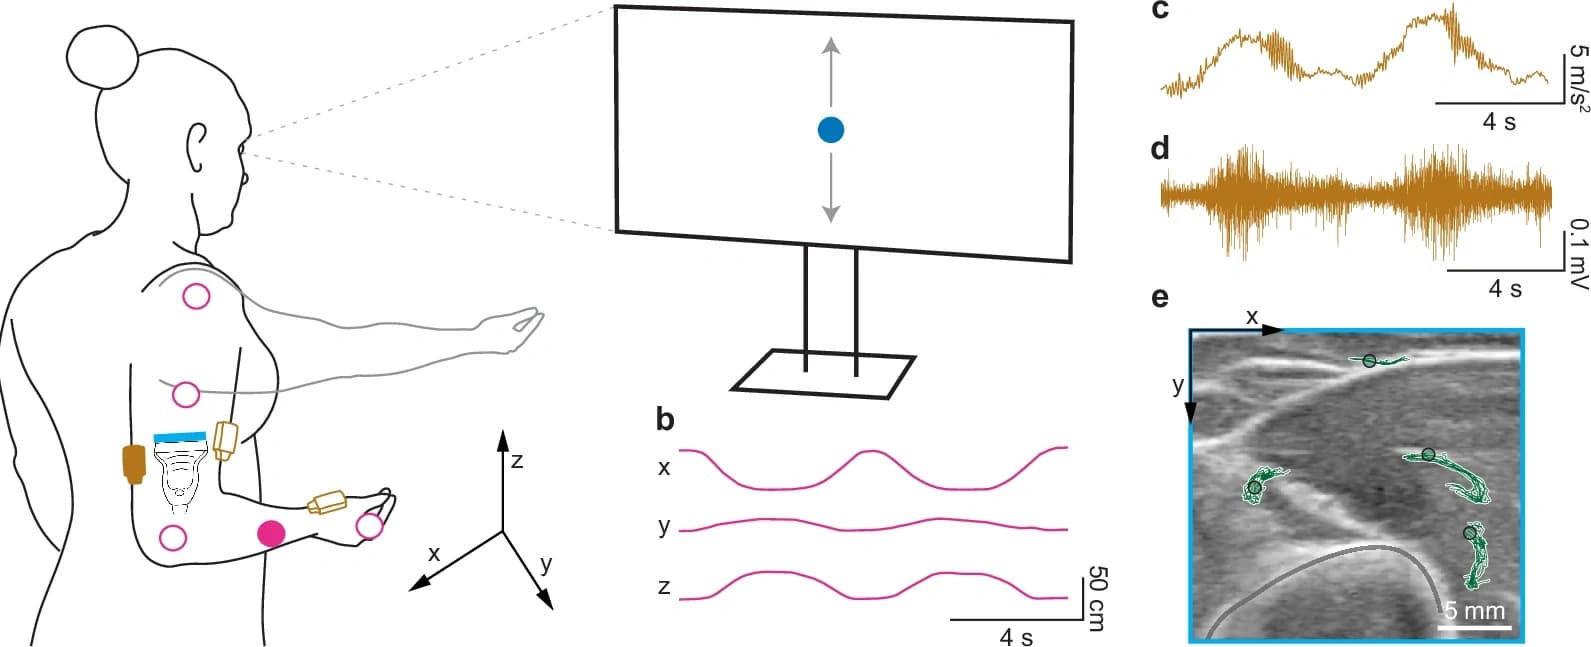
Match4Annotate transfers user-defined point and mask annotations from a labeled ultrasound video to independently acquired target videos without target-side labels or manual initialization. The method combines continuous spatiotemporal DINOv3 feature fields with implicit feature flow, aligning anatomy in feature space rather than relying on ultrasound intensity. Across four cardiac and musculoskeletal datasets, it achieves state-of-the-art cross-video annotation transfer and can reuse annotations across datasets with different labeling protocols, without task-specific training.
Paper Code · coming soon